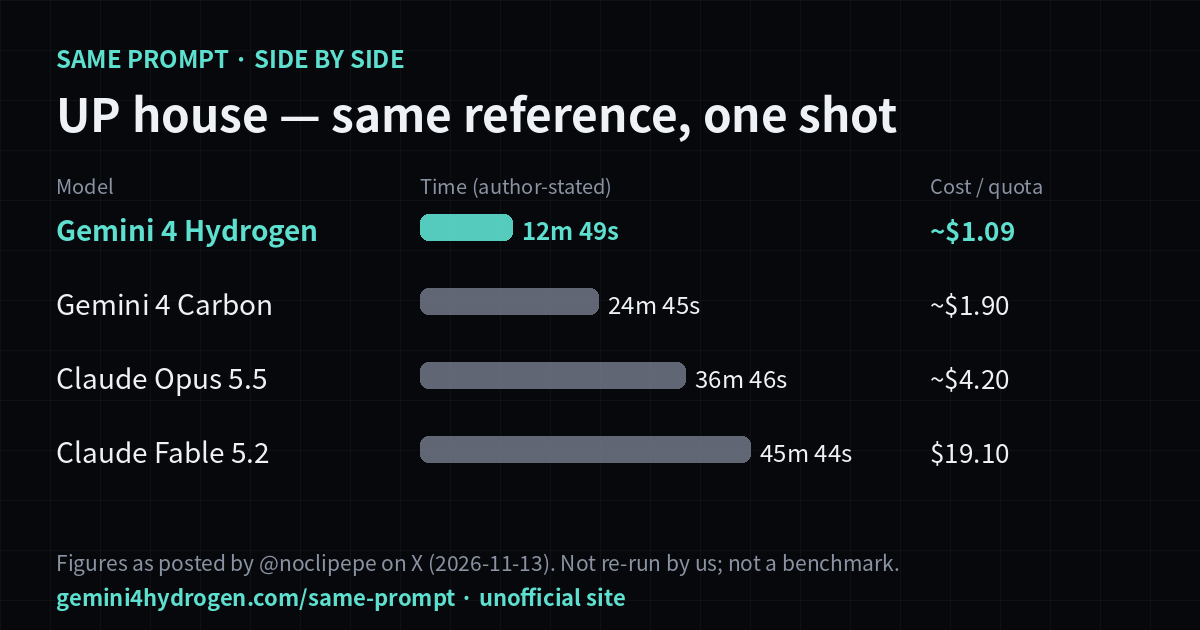
Gemini 4 Hydrogen vs Claude Opus 5.5
Google has not published a Hydrogen-vs-Opus 5.5 benchmark. On list price, Opus 5.5 is $4 / $20 per 1M input/output tokens versus Hydrogen’s $1.50 / $7.50 — about 2.7× more. On the independent Artificial Analysis Intelligence Index, Opus 5.5 (max) scores 59 and Hydrogen 54 at xhigh. Google’s own counterpart to Opus is Gemini 4 Carbon (AA 60 at high), which moves to the same $4 / $20 list price on 1 December 2026.
Prices are official list prices retrieved 13 November 2026. Artificial Analysis Intelligence Index figures are from Artificial Analysis model pages retrieved the same day (Hydrogen high = 51 is Google’s citation in its announcement). This site has not run these models. Source: Google AI Studio / Gemini API docs, Retrieved 13 November 2026 · Source: Anthropic, Retrieved 13 November 2026 · Source: Google Blog, 12 November 2026
Official list prices, retrieved 13 November 2026; AA = Artificial Analysis Intelligence Index. | Gemini 4 Hydrogen | Claude Opus 5.5 | Gemini 4 Carbon |
|---|
| Input / 1M | $1.50 | $4 | $2 through 30 Nov 2026, then $4 |
|---|
| Output / 1M | $7.50 | $20 | $10 through 30 Nov 2026, then $20 |
|---|
| Cache hits / 1M | $0.075 | $0.20 (0.05× base input) | $0.10, then $0.20 |
|---|
| Free API tier | Yes (rate-limited) | Free credits for new users | Not available |
|---|
| AA Intelligence Index | 54 (xhigh) · 51 (high) — AA | 59 (max) — AA | 60 (high) — AA |
|---|
Cost example (our arithmetic)
10M input + 2M output tokens: Hydrogen $30; Opus 5.5 10 × $4 + 2 × $20 = $80; Carbon $40 in November and $80 from December. Per-token prices are not perfectly comparable across vendors: Anthropic’s pricing page says Claude 4.7 and later models use a newer tokenizer that produces about 30% more tokens for the same text.
How Google suggests splitting the work
Google positions Hydrogen as the fast execution model and Carbon/Argon as frontier models for deep, long-horizon reasoning. Its announcement describes Carbon coordinating while Hydrogen powers worker and verifier agents, and says Orchestrator in Antigravity reached near-Carbon task success on Terminal-Bench 4.0 while using 24% less quota and finishing 19% faster. A similar split (frontier planner, cheaper executor) is a common way to use Opus-class models too, but no published test compares Hydrogen and Opus 5.5 directly. Source: Google Blog, 12 November 2026
More comparisons vs Claude Sonnet 5.5 vs GPT-6.1 Sol vs Gemini 3.1 Pro vs 3.8 Flash vs Argon / Carbon All benchmarks Pricing
Have you tried Hydrogen against one of these? Submit your case — real public posts get listed and ranked.
Speed, tokens per second and cost per task
At its default high level, Hydrogen measured 171 output tokens/s and 8.3 minutes per Artificial Analysis Index task; the fastest level of the other models here measured 114 tok/s, so Hydrogen streamed about 1.5× as fast in AA’s runs.
Measured independently by Artificial Analysis on each vendor's own API (retrieved 14 November 2026); speed is averaged over the past 5 days and changes. A dash means AA had not published that figure. This site did not run these tests.| Model · thinking/effort level | AA Intelligence Index | Output speed (tok/s) | Minutes per AA Index task | Time to first answer token (s) |
|---|
| Gemini 4 Hydrogen · xhigh | 54 | 178 | 14.5 | 44.79 |
|---|
| Gemini 4 Hydrogen · high | 51 | 171 | 8.3 | 17.37 |
|---|
| Gemini 4 Hydrogen · medium | 41 | 174 | 3.8 | 11.81 |
|---|
| Gemini 4 Hydrogen · low | 27 | 173 | 1.4 | 5.58 |
|---|
| Claude Opus 5.5 · max | 59 | 114 | 25.4 | 396.07 |
|---|
| Claude Opus 5.5 · xhigh | 57 | 110 | 15.7 | 88.46 |
|---|
| Claude Opus 5.5 · high | 52 | 106 | 9.5 | 27.87 |
|---|
| Claude Opus 5.5 · medium | 48 | 105 | 6.9 | 17.60 |
|---|
| Claude Opus 5.5 · low | 35 | 105 | 3.0 | 5.02 |
|---|
| Gemini 4 Carbon · high | 60 | 66 | 30.9 | 70.53 |
|---|
| Gemini 4 Carbon · medium | 58 | 61 | 27.9 | 22.18 |
|---|
| Gemini 4 Carbon · low | 54 | 51 | 28.0 | 13.89 |
|---|
The task-cost columns are our arithmetic on official list prices, assuming every model uses the same token counts — they do not (see output volume below), and Anthropic says its newer tokenizer produces about 30% more tokens for the same text. No cache, batch, or grounding fees. The last column is Artificial Analysis’s own measured average, at the prices AA used, for the variant named in brackets.| Model | Official list price (input / output per 1M) | Our arithmetic per task (50K in + 8K out) | ×1,000 tasks | AA measured cost per Index task |
|---|
| Gemini 4 Hydrogen | $1.50 / $7.50 flat | $0.135 | $135 | $3.16 (xhigh) |
|---|
| Claude Opus 5.5 | $4 / $20 | $0.360 | $360 | $10.04 (max) |
|---|
| Gemini 4 Carbon | $2 / $10 through 30 Nov 2026; $4 / $20 from 1 Dec 2026 | $0.180 (to 30 Nov 2026)
$0.360 (from 1 Dec 2026) | $180
$360 | $5.48 (high) |
|---|
Output tokens Artificial Analysis recorded while running its whole Intelligence Index (more tokens = more cost and time for the same work): Gemini 4 Hydrogen: xhigh 304M, high 110M, medium 54.4M, low 20.3M; Claude Opus 5.5: max 218M, xhigh 101M, high 56.1M, medium 42.5M, low 21.1M; Gemini 4 Carbon: high 205M, medium 124M, low 83.9M.
Source: Artificial Analysis: Gemini 4 Hydrogen · Artificial Analysis: Claude Opus 5.5 · Artificial Analysis: Gemini 4 Carbon (retrieved 14 November 2026) · Source: Google AI Studio / Gemini API docs, Retrieved 13 November 2026
Plug in your own token counts: Hydrogen cost calculator · all comparisons.