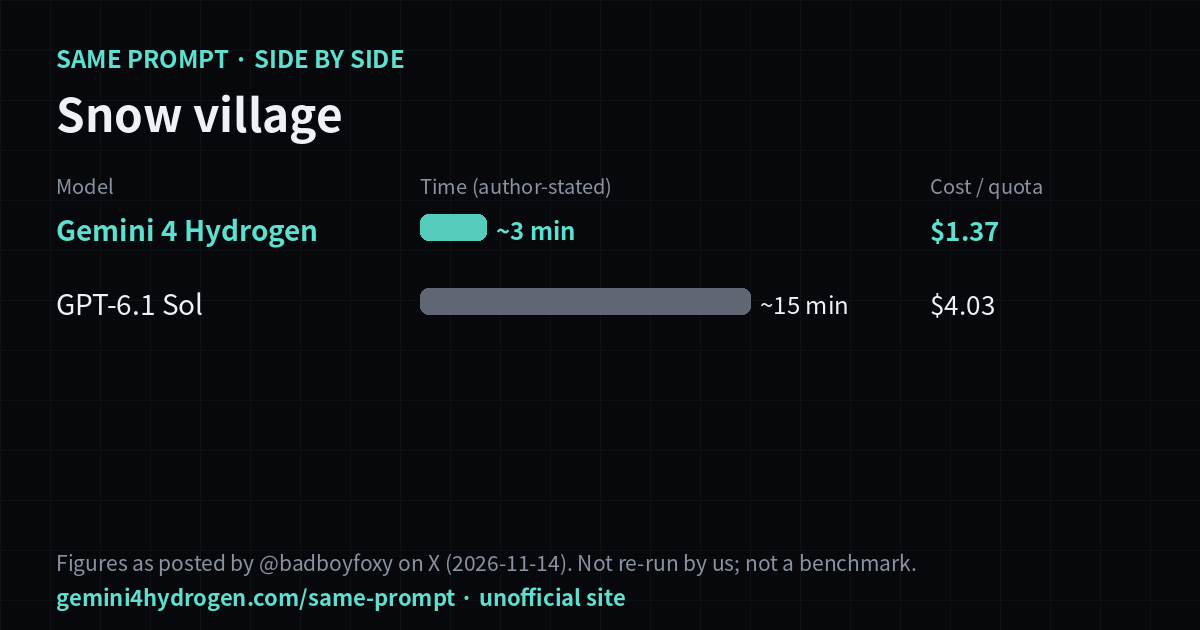
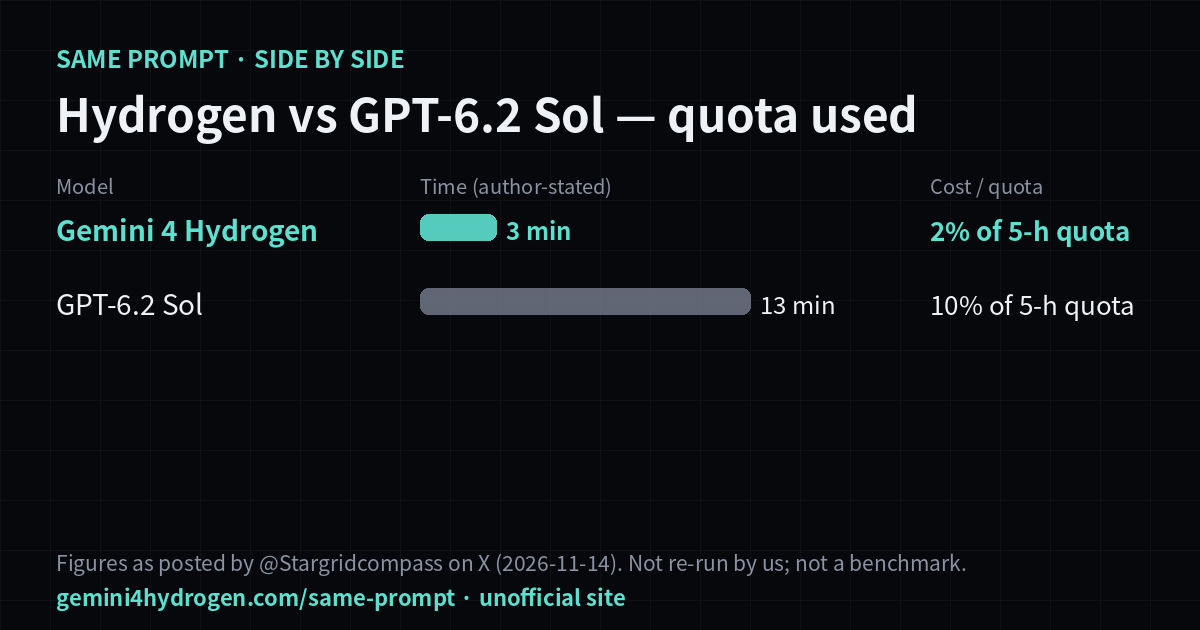
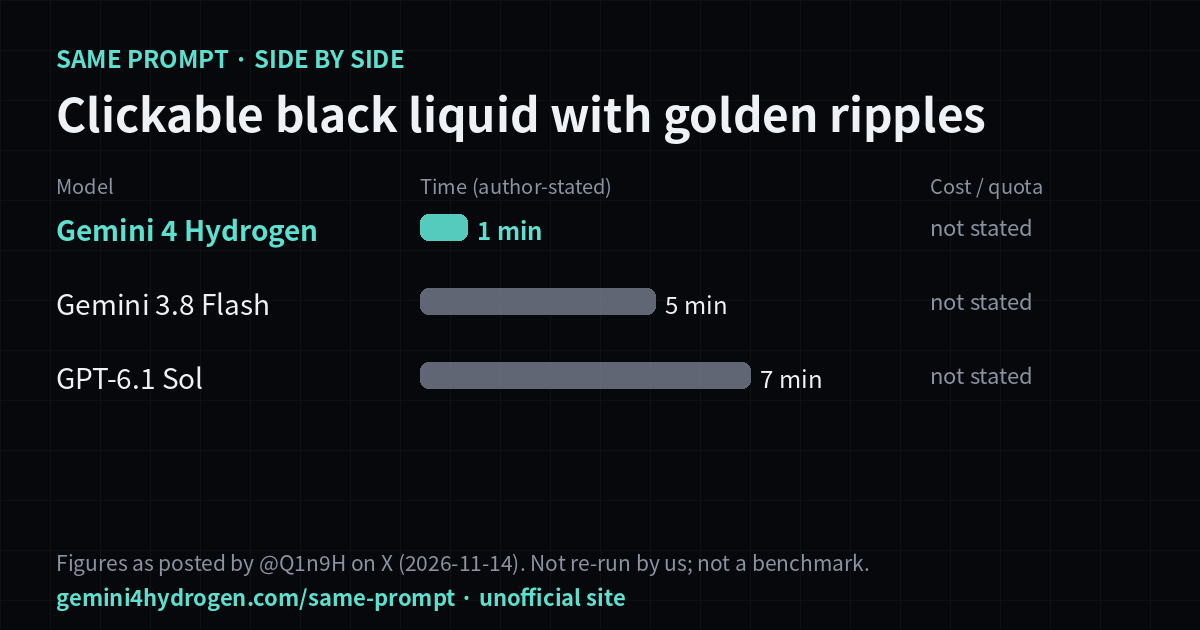
Gemini 4 Hydrogen vs GPT-6.1 Sol
GPT-6.1 Sol lists at $2 / $10 per 1M input/output tokens for prompts up to 272K tokens and $4 / $15 above that; Hydrogen is a flat $1.50 / $7.50 across its full 1M window. Artificial Analysis scores Sol (max) at 55 and Hydrogen at 54 (xhigh). Google’s model card compares Hydrogen with GPT-6.1 Terra, not Sol.
Prices are official list prices retrieved 13 November 2026. Artificial Analysis Intelligence Index figures are from Artificial Analysis model pages retrieved the same day (Hydrogen high = 51 is Google’s citation in its announcement). This site has not run these models. Source: Google AI Studio / Gemini API docs, Retrieved 13 November 2026 · Source: OpenAI, Retrieved 13 November 2026 · Source: Google DeepMind, 12 November 2026
Official standard list prices, retrieved 13 November 2026. | Gemini 4 Hydrogen | GPT-6.1 Sol | GPT-6.1 Terra |
|---|
| Input / 1M (≤272K prompt) | $1.50 (flat to 1M) | $2 | $1 |
|---|
| Output / 1M (≤272K prompt) | $7.50 (flat to 1M) | $10 | $5 |
|---|
| Input / output above 272K | same flat price | $4 / $15 | $2 / $7.50 |
|---|
| Cached input / 1M | $0.075 | $0.10 (short) / $0.20 (long) | $0.05 / $0.10 |
|---|
| AA Intelligence Index | 54 (xhigh) · 51 (high) — AA | 55 (max) — AA | 51 (max) — AA |
|---|
Cost example (our arithmetic)
10M input + 2M output tokens with short prompts: Hydrogen $30; Sol 10 × $2 + 2 × $10 = $40; Terra $20. If every prompt is over 272K tokens, Sol becomes 10 × $4 + 2 × $15 = $70 while Hydrogen stays $30.
Published head-to-head (Terra, not Sol)
In Google’s model-card table Hydrogen scores higher than GPT-6.1 Terra on eight of the nine rows where both have a score (for example SWE-sweep 13.5% vs 5.8%, AutomationBench-AA 76.1% vs 60.2%, HLE-Diamond 58.8% vs 47.3%); Terra leads on Terminal-Bench-Science 0.1 (58.3% vs 51.4%). Terra has no Terminal-Bench 4.1 figure in that table. No Google-published table includes Sol. See the full table. Source: Google DeepMind, 12 November 2026
More comparisons vs Claude Sonnet 5.5 vs Claude Opus 5.5 vs Gemini 3.1 Pro vs 3.8 Flash vs Argon / Carbon All benchmarks Pricing
Have you tried Hydrogen against one of these? Submit your case — real public posts get listed and ranked.
Speed, tokens per second and cost per task
At its default high level, Hydrogen measured 171 output tokens/s and 8.3 minutes per Artificial Analysis Index task; the fastest level of the other model here measured 49 tok/s, so Hydrogen streamed about 3.5× as fast in AA’s runs.
Measured independently by Artificial Analysis on each vendor's own API (retrieved 14 November 2026); speed is averaged over the past 5 days and changes. A dash means AA had not published that figure. This site did not run these tests.| Model · thinking/effort level | AA Intelligence Index | Output speed (tok/s) | Minutes per AA Index task | Time to first answer token (s) |
|---|
| Gemini 4 Hydrogen · xhigh | 54 | 178 | 14.5 | 44.79 |
|---|
| Gemini 4 Hydrogen · high | 51 | 171 | 8.3 | 17.37 |
|---|
| Gemini 4 Hydrogen · medium | 41 | 174 | 3.8 | 11.81 |
|---|
| Gemini 4 Hydrogen · low | 27 | 173 | 1.4 | 5.58 |
|---|
| GPT-6.1 Sol · max | 55 | 49 | 23.3 | 201.02 |
|---|
| GPT-6.1 Sol · xhigh | 52 | 47 | 10.7 | 85.75 |
|---|
| GPT-6.1 Sol · high | 50 | 48 | 7.9 | 43.12 |
|---|
| GPT-6.1 Sol · medium | 46 | 49 | 4.6 | 5.27 |
|---|
| GPT-6.1 Sol · low | 35 | 48 | 2.0 | 3.14 |
|---|
The task-cost columns are our arithmetic on official list prices, assuming every model uses the same token counts — they do not (see output volume below), and Anthropic says its newer tokenizer produces about 30% more tokens for the same text. No cache, batch, or grounding fees. The last column is Artificial Analysis’s own measured average, at the prices AA used, for the variant named in brackets.| Model | Official list price (input / output per 1M) | Our arithmetic per task (50K in + 8K out) | ×1,000 tasks | AA measured cost per Index task |
|---|
| Gemini 4 Hydrogen | $1.50 / $7.50 flat | $0.135 | $135 | $3.16 (xhigh) |
|---|
| GPT-6.1 Sol | $2 / $10 (≤272K); $4 / $15 above | $0.180 (≤272K prompt) | $180 | $1.27 (max) |
|---|
Output tokens Artificial Analysis recorded while running its whole Intelligence Index (more tokens = more cost and time for the same work): Gemini 4 Hydrogen: xhigh 304M, high 110M, medium 54.4M, low 20.3M; GPT-6.1 Sol: max 63.7M, xhigh 33.3M, high 24.7M, medium 15.1M, low 8.18M.
Source: Artificial Analysis: Gemini 4 Hydrogen · Artificial Analysis: GPT-6.1 Sol (retrieved 14 November 2026) · Source: Google AI Studio / Gemini API docs, Retrieved 13 November 2026
Plug in your own token counts: Hydrogen cost calculator · all comparisons.